What do cleanup and crosstalk mean in HDC?
A look back at how the HDC literature describes the terms "cleanup" and "crosstalk", and how we can view both terms through a modern lens using vector search in LanceDB.
On this page
In earlier posts, we saw how HDC can bundle a whole record’s facts into a single hypervector, while still making it queryable to retrieve specific facts. In this post, we look deeper at how a retrieved result from a bundle is not an exact match, because the other facts stored alongside it interfere with the result.
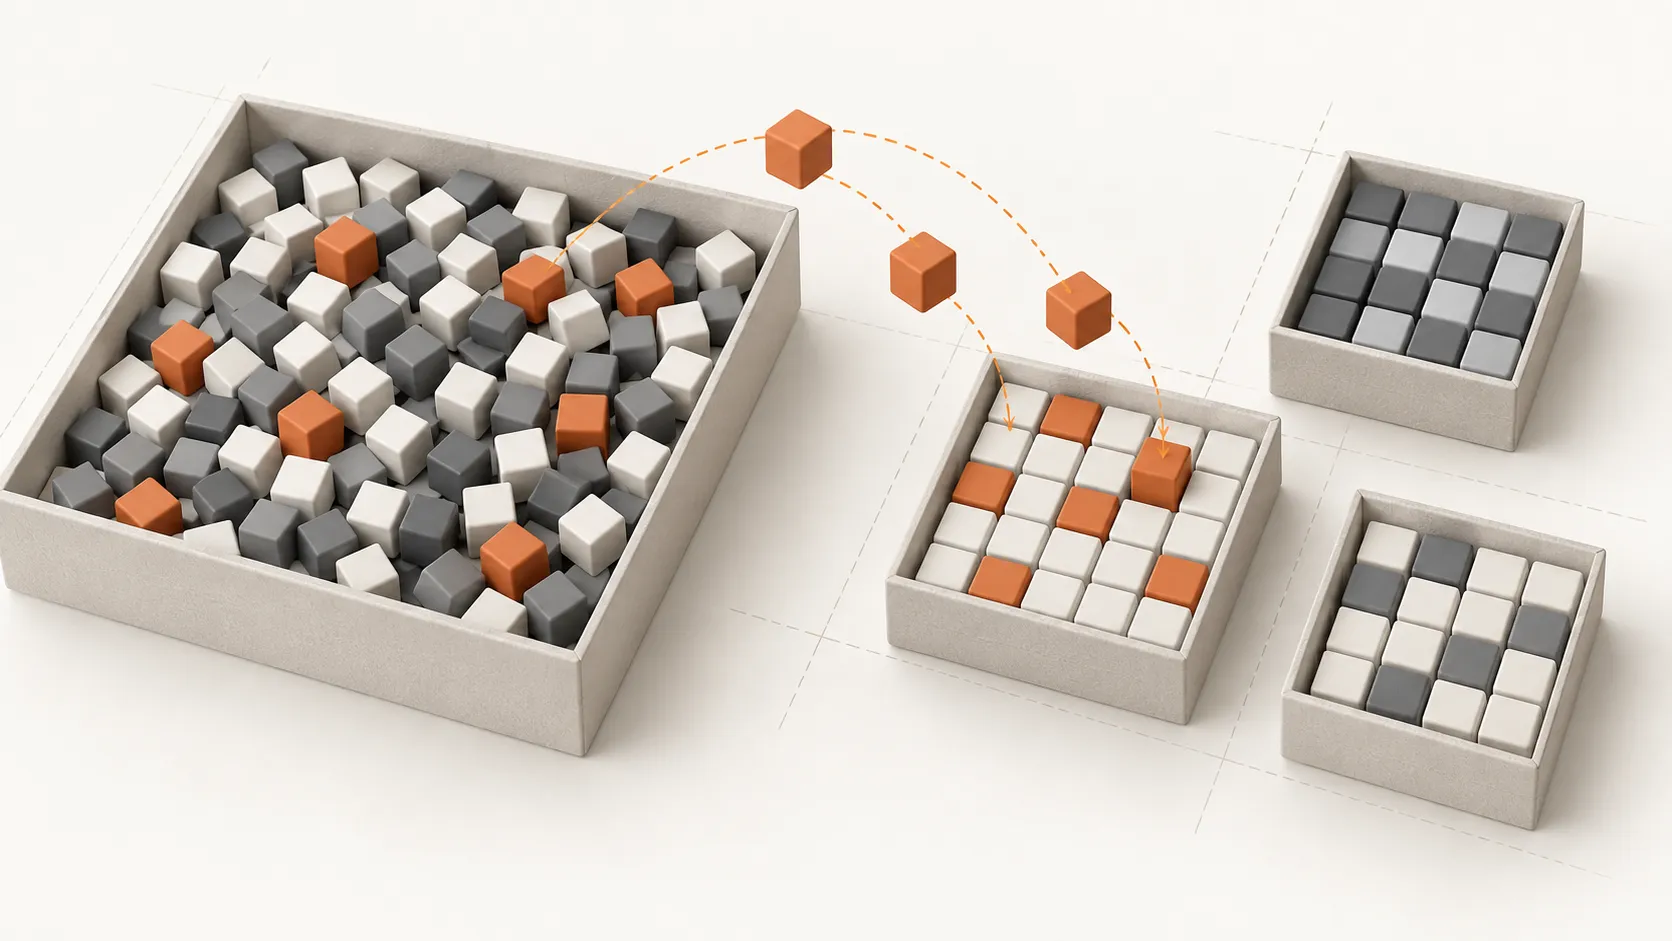
The HDC literature commonly uses the term cleanup (which has nothing to do with data cleaning or deduplication) to describe what happens when we take an approximate hypervector and return the stored hypervector it most likely stands for.
The term crosstalk is used to describe the interference that occurs when multiple facts share a single hypervector. We’ll explore that term later in this post. The central idea being conveyed here is that “cleanup” shouldn’t be thought of as another HDC primitive alongside binding, bundling, and permutation. In practice, cleanup is fundamentally a retrieval problem that can benefit from modern retrieval methods like metadata filtering and lookup.
Much of what the HDC literature describes will look very familiar if you view it through the lens of a modern vector retrieval system like LanceDB. We’ll demonstrate these ideas by creating a query hypervector, searching over a collection of canonical stored hypervectors, and retrieving whichever stored item is most similar to the query.
A simple example
Let’s return to the two people we used when asking what we can recover from a bundled hypervector. Maya and Nina are each described by an age, an eye color, and three interests:
| Person | Age | Eye color | Interests |
|---|---|---|---|
| Maya | 34 | Brown | Tea, climbing, jazz |
| Nina | 33 | Blue | Tea, cooking, photography |
As before, we embed each value with nomic-embed-text, project the embedding up to 4,096 dimensions with a fixed random matrix, and keep only the sign of each component while preserving the structure captured by the underlying embedding.1 Each field (age, eye color, and interest) gets its own random bipolar role hypervector, and we bind (, element-wise multiplication) every value to the role of its field.
We construct the hypervector for the person “Maya” by bundling the five bound facts that we have on her:
Here, denotes bundling. When writing to storage, we keep the raw sums from the additive operations rather than signing the bundle back to . All five of Maya’s facts now share one 4,096-dimensional hypervector, and Nina’s record follows the same structure.
What do we get if we try to recover Maya’s eye color by just encoding the eye-color role as the query hypervector?
Cleanup is not needed with pure binding
Taken on its own, a single fact, such as Maya’s eye-color, is bound as a role-value pair to hypervector that’s exactly reversible. Unbinding it with the same role again recovers the original value (in MAP). Every component of a bipolar hypervector is , so multiplying the role by itself gives the all-ones hypervector , which leaves anything it’s bound to unchanged:
When we run this kind of query on our stored hypervectors, we recover the exact hypervector for brown eyes. There’s nothing to “clean up”, yet.
When doing pure binding and unbinding, the algebra is exactly reversible. The approximate answer that needs to be cleared up only appears when we bundle multiple facts together, because the other facts interfere with the one we’re trying to recover.
Bundling blurs the answer
Let’s see what happens when we query the full hypervector for Maya, which bundles her eye color, age and interests. The goal is to simply recover her eye color via a query.
To construct the query hypervector, we first bind the whole bundle with the eye-color role, an operation the HDC literature calls a role probe. Because binding distributes over these raw-sum bundles, the role hypervector multiplies into every one of the five facts:
The first term is the exact hypervector for brown eyes, since the eye-color role cancels itself there due to the reversibility of binding. However, the other four facts also come along for the ride: each scrambled by a pair of different roles that don’t cancel out. We can collect them all into one “interference” term:
The interference is far from small. Instead of , the probe’s components now range from to , and its cosine similarity with the stored brown eyes hypervector is only 0.37. The probe is brown-eyes-ish, so how do we turn it back into the actual known item, brown eyes? We’re now starting to see why the HDC literature talks about “cleanup” as a separate step.
What older papers called cleanup
HDC’s early researchers ran into this question decades ago, well before the advent of modern vector databases. Tony Plate’s 1995 paper2 on Holographic Reduced Representations (HRR) noted that noisy reconstructions “can be cleaned up by using a separate associative memory that has good reconstructive properties.” For Plate, cleanup sat outside the algebra, as a lookup in a memory of known items.3
Pentti Kanerva’s 2009 introduction to hyperdimensional computing4 gave this memory the name most people know today. Every meaningful hypervector gets recorded in an item memory, which hands back the stored, noise-free pattern when queried with a noisy one. Kanerva describes its job as “nearest-neighbor search among the set of stored (meaningful) patterns,” which is why it’s also called a clean-up memory.
As anyone who’s built a retrieval-augmented generation (RAG) system would recognize, we have a simple solution to performing vector-based lookup today. Nearest-neighbor search over stored vectors is exactly what a vector database is built to do. From an HDC perspective, can similarity-based retrieval perform the role of clean-up memory?
Viewing cleanup through the lens of vector search
Let’s understand how cleanup would work in LanceDB. We store Maya and Nina as ordinary rows in a people table, with their bundled hypervectors5 in a column named hv:
| person_id | age | eye_color | interests | hv (4,096 values) |
|---|---|---|---|---|
| maya | 34 | brown | [tea, climbing, jazz] | [3, −5, −3, 5, −1, 1, …] |
| nina | 33 | blue | [tea, cooking, photography] | [5, −5, 1, 5, −1, 1, …] |
We also store the hypervector of each known eye color in a small eye_color table:
| value | hv (4,096 values) |
|---|---|
| brown eyes | [−1, 1, 1, 1, −1, 1, …] |
| blue eyes | [1, 1, −1, 1, −1, 1, …] |
The eye_color table serves as the “cleanup memory” for this field: it gives the search a set of valid answers, each with a readable label and an exact hypervector. Separate age and interests tables serve the same purpose for those fields. Each table grows with the number of distinct values, so even 10,000 hobbies would need only 10,000 rows in interests.
Maya’s approximate eye-color answer becomes our search query. First, we generate the query hypervector by unbinding the eye-color role from the full bundled hypervector.
# Query Maya's record for her eye color by unbinding the eye-color role.
eye_query = eye_role * maya_hv
In mathematical terms, the query hypervector shown above as Python code is the eye-color role bound to Maya’s bundled hypervector, expressed as follows:
With the example tables stored in a local LanceDB database, we can search the known eye colors for the closest match:
import lancedb

# Open the database and the table of known eye colors.
db = lancedb.connect("example.lancedb")
eye_color_tbl = db.open_table("eye_color")

# Compare the TorchHD query with known eye colors
# LanceDB takes a list, so we convert the TorchHD tensor to a list.
matches = (
    eye_color_tbl.search(
        eye_query.tolist(),
        vector_column_name="hv"
    )
    .distance_type("cosine")
    .to_list()
)

# For this example, use the winning row's stored hypervector as the clean value.
clean_eye_hv = matches[0]["hv"]
Maya’s query is closer to brown eyes than blue eyes, with cosine similarities of 0.37 and 0.20.
What Plate described as a separate associative memory is, in LanceDB terms, the two-row eye_color table. One line of a search and lookup query takes us from a noisy, “brown-eyes-ish” hypervector to the exact brown eyes entry, with its label and original hypervector included.
That label also serves as a nice lookup field to the rest of the database. The people table stores the eye color as brown, so a metadata filter lookup in LanceDB can now retrieve every complete record with that value, including Maya’s:
# Use the recognized eye color as an exact filter over the people table.
people = db.open_table("people")
people.search().where("eye_color = 'brown'").to_list()
In this simple two-person database, Maya is the only match. The filter returns her complete row: 34 years old, brown eyes, and interests in tea, climbing, and jazz.
In a larger people table for a realistic dataset, the same filter might match thousands of rows. We could add a vector query for an interest like jazz and take the top-k, keeping only the most relevant people with brown eyes.
What crosstalk is and how we handle it
LanceDB makes the lookup easy, enabling us to implement cleanup strategies. However, there’s another issue with dealing with bundled representations: The eye-color query found a person with brown eyes, which we then used to retrieve the full row with a metadata filter lookup in LanceDB. But the query vector was still far from the stored brown-eyes hypervector: their cosine similarity was 0.366 rather than 1.000. Why was it so far from an exact match, despite having the correct label in its hypervector?
When we ask for eye color, the brown-eyes hypervector comes back mixed with contributions from the other four facts for Maya (her age and her 3 interests). HDC calls this interference crosstalk. It makes the correct label “brown eyes” harder to distinguish from other possible answers, due to the superposition.
If blue eyes were to rank first, accepting the top result would give us the wrong label, and the metadata filter could lead us to Nina instead of Maya. The brown-eyes fact would still be in Maya’s bundle, but that lookup would have failed to recover it.
The term crosstalk traces back to the field of communications, where a voice on one telephone line could leak into another. In Maya’s query, the unwanted voices are facts from her own record. Crosstalk also appears in earlier associative-memory research. In his 1972 work on correlation matrix memories, Teuvo Kohonen described how recalling one stored pattern could pick up contributions from others when their keys were not orthogonal.6
We can see the effect of crosstalk in practice using LanceDB. Using the same stored hypervectors and roles, we rebuild Maya’s bundle with one, two, or all five facts. For each version, we ask for her eye color and search the two known eye colors by exact cosine similarity:
| Facts in Maya’s bundle | Brown eyes | Blue eyes | Brown’s lead |
|---|---|---|---|
| Eye color only | 1.000 | 0.596 | 0.404 |
| Eye color and age | 0.717 | 0.422 | 0.295 |
| All five facts | 0.366 | 0.203 | 0.162 |
With eye color alone, the query exactly matches brown eyes. Adding the other four facts reduces its similarity from 1.000 to 0.366 and narrows its lead over blue eyes from 0.404 to 0.162. Brown eyes still wins. This is what we refer to as graceful degradation: despite the query result being blurred by the noise, the search still retrieves Maya’s correct eye color because the hypervector captures the differences well enough.
In practice, crosstalk can push relevant results down the ranking when we search their bundled hypervectors and the interference is large enough. This is why it makes sense to always measure the intended result’s rank and its lead over other candidates on representative queries from the actual dataset, as part of the evaluation suite. We’d then tune hypervector dimensionality (increasing it if required) and increase the level of detail in our encodings and queries, checking whether those choices keep retrieval useful as bundles grow.
Conclusions
In this post, we worked through a concrete understanding of two ideas that are common in bundled representations in HDC: cleanup and crosstalk. THe following ideas tie the journey together:
- Bundling superimposes several facts into a single hypervector.
- Crosstalk is the interference we run into from the other facts when we try to recover one of them.
- Cleanup is the retrieval step that maps the approximate result back to a known value.
When first meeting the term cleanup in older HDC literature, it’s natural to wonder “how is cleanup done, and why do I need it?” The key thing to takeaway is that the term cleanup originated at a time that predates modern vector databases, where the answer to a question often came out of the algebra itself, with no stored row to read it from.
Say a similarity search returns a handful of people. To find the interest they share, we add their bundled hypervectors together, bind the sum with the interest role, and clean up the result against the interests table. For Maya and Nina, this ranks tea first (0.74), ahead of cooking (0.67), and tea is the one interest they share. No row in people stores “the interest these people have in common”, so cleanup is the only way to read it, and on a result set of hundreds of people, it summarizes the whole group without scanning every row.
Crosstalk is simply the interference that blurs a particular fact due to the presence of other facts, and thus also blurs the similarity scores a search app ranks by, so it decides how much we can pack into a bundle and still trust the results.
With LanceDB, all it takes is a simple lookup by metadata filter once you retrieve the most similar result. Even if a retrieved result contains noise, using a combination of metadata filters and cleanup steps can help us retrieve the most relevant information. Much of what sounds abstract in the older HDC literature turns out to be everyday retrieval engineering.
In our next post, we’ll put some of these ideas to the test by packing up to 50 facts into one bundle and measuring how well we can recover them despite crosstalk. Stay tuned!
Footnotes
-
We use FastEmbed’s
nomic-ai/nomic-embed-text-v1.5-Qwith thesearch_document:prefix, a seeded Rademacher projection (entries ) from 768 to 4,096 dimensions, and independent random bipolar roles, with the seed set to 2026. This run uses FastEmbed’s quantized build of the model rather than the Ollama build from our earlier post, so individual scores differ slightly from the ones reported there. ↩ -
Tony A. Plate, “Holographic Reduced Representations,” IEEE Transactions on Neural Networks, 6(3), 1995, pp. 623 to 641, doi:10.1109/72.377968. Section IV is titled “The need for reconstructive item memories.” ↩
-
Here, “memory” doesn’t mean RAM or a cache; it means a store of known patterns that we query by their content, rather than by an address. ↩
-
Pentti Kanerva, “Hyperdimensional Computing: An Introduction to Computing in Distributed Representation with High-Dimensional Random Vectors,” Cognitive Computation, 1(2), 2009, pp. 139 to 159. The item memory is described in Section 6.1. ↩
-
LanceDB stores the hypervectors as float16, which represents values and small integer sums exactly. We cast back to float32 for all computation. ↩
-
Teuvo Kohonen, “Correlation Matrix Memories” (open-access scan), IEEE Transactions on Computers, C-21(4), 1972, pp. 353 to 359, doi:10.1109/TC.1972.5008975. See p. 354 for the discussion of crosstalk from nonorthogonal key vectors. ↩