Introduction to Hyperdimensional Computing
A gentle introduction to how hyperdimensional computing represents, combines, and retrieves information using high-dimensional hypervectors.
On this page
What is Hyperdimensional Computing?
Hyperdimensional Computing (HDC) is a computational paradigm that processes information using very high-dimensional representations, often with thousands or tens of thousands of dimensions.
These large patterns, called hypervectors, give us a common mathematical space for encoding, composing, and retrieving information. An encoder builds fixed representations from the entities and relationships already present in the data, allowing us to bake in human domain knowledge as part of the process. We can then work with those representations using a small set of algebraic operations.
HDC has its roots in cognitive science and takes inspiration from the way the brain works by defining large, distributed and redundant patterns. While it’s not a literal model of the brain, the comparison is useful because HDC can distribute information across a representation, retrieve a memory from a partial cue, and incorporate new examples without always retraining an entire model.
We’ll keep this first post brief, covering one simple example and just enough math to demonstrate the key ideas. The next two posts cover what hypervectors are and why their distributed, or “holographic,” nature is useful.
How HDC differs from representation learning
A good way to begin appreciating HDC is to contrast it with the more familiar approach of end-to-end representation learning, especially deep learning. In an end-to-end ML system, a model learns its internal representation from training data. In HDC, the representation is fixed: we explicitly define how the parts and relationships in our data are represented, and then compose them using a simple algebra.
End-to-end representation learning has proven effective in practice. Depending on the problem, though, it may also involve the following challenges:
- Large datasets and substantial training time
- Learned representations that are difficult to inspect and explain
- More complex retraining or fine-tuning as new examples arrive
- Models that are difficult to run on constrained hardware
In comparison with representation learning, HDC has a different set of properties that can be very useful in practice:
- Information is distributed across many dimensions, so modest amounts of noise usually change similarity gradually.
- Roles and relationships are retained because we can combine them and operate over them with a small algebra.
- A partial or noisy cue can retrieve a related representation without requiring an exact match, making search & retrieval systems more robust.
- New examples can update a class prototype or memory as they arrive, enabling online/continuous learning.
- The underlying hypervector operations are simple, and parallelized hardware can often run them efficiently, without requiring too much compute.
It’s important to note that HDC isn’t a replacement for deep learning models in every setting. With the right representation, hardware, and task definition, it can complement other methods, or even replace them in some cases.
How does Hyperdimensional Computing work?
There isn’t one universal way to build an HDC pipeline. In this intro post, we’ll follow one simple approach built around a small example. Say we have a Person profile with three facts:
- The person’s name is Maya
- Maya is interested in hiking
- Maya is interested in music
This simple dataset can be represented using basic symbols for each role or fact, such as name, interest, Maya, and hiking, and then modeled as hypervectors. We’ll use for a role and for a value. For now, suffice to say that we use an encoder to map each symbol to a hypervector in the same high-dimensional space. We’ll cover more details about encoders in future posts.
The goal here is to preserve the roles in each fact. A role and its value should remain clearly separated in the representation: even if two roles share the same value, the concepts should be distinguishable.
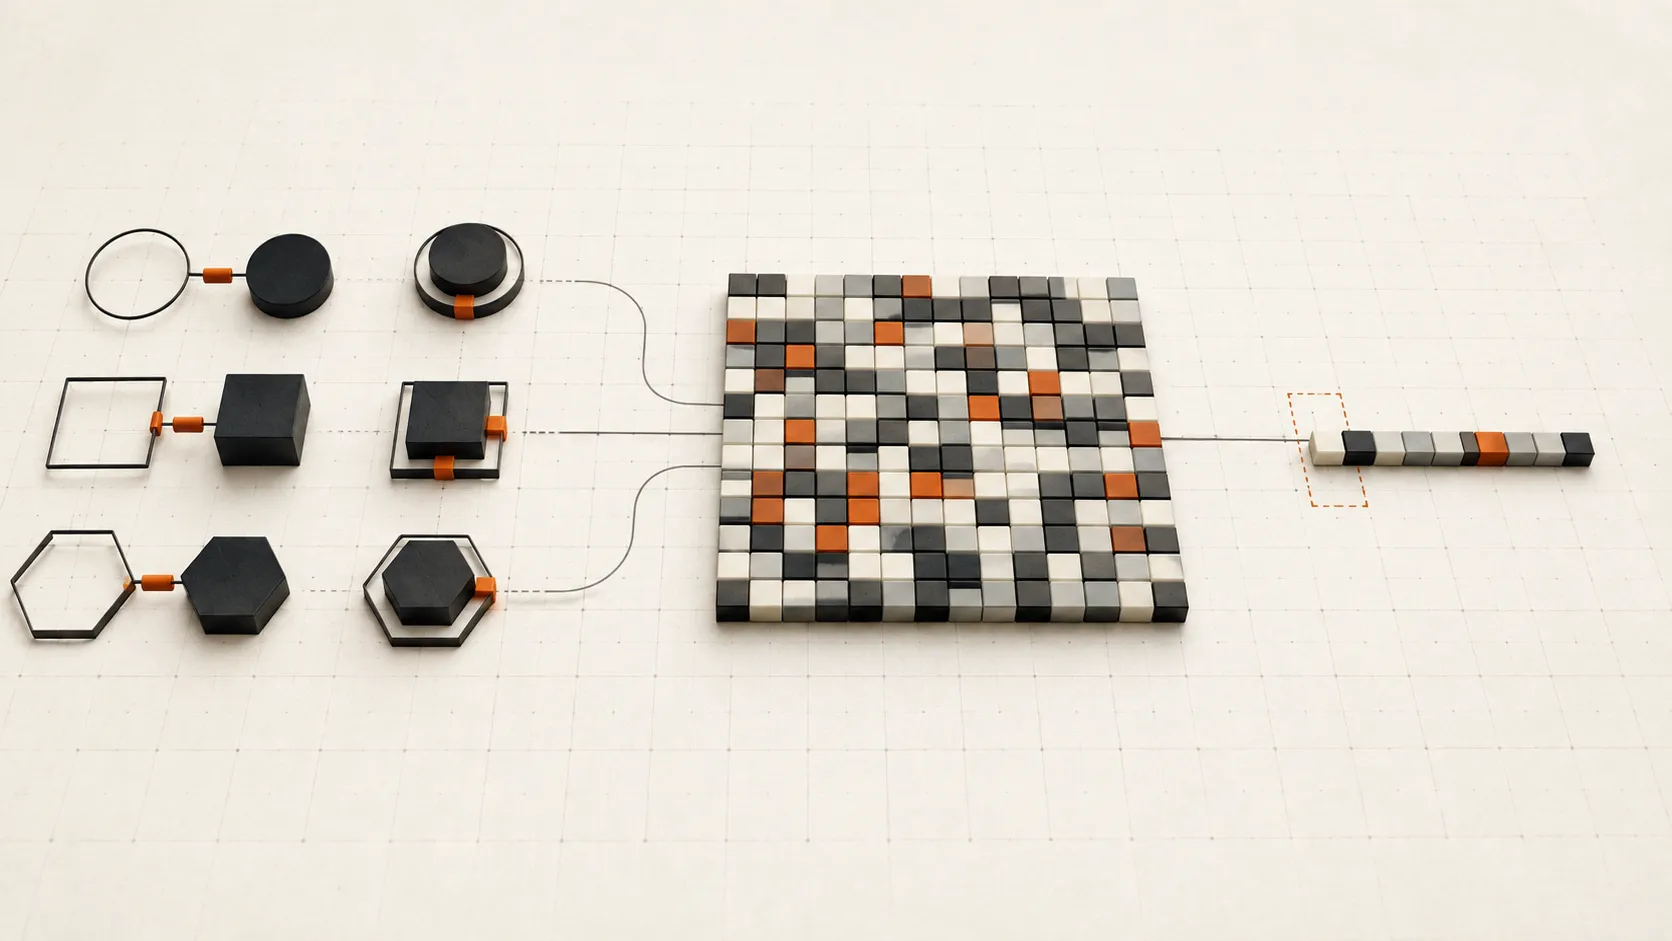
To accomplish that, HDC uses an operation called binding, which associates a role with a value:
is read as “bound with,” so the first equation says, “the role name is bound with the value Maya.” Binding turns a role and value into one hypervector that represents their association.
We now have three fact hypervectors that each contain Maya’s name and her interests. To represent Maya’s whole profile, we use another operation called bundling, which resembles superposition:
Each fact is combined to form a single, new pattern that retains similarity to the original. Binding forms the associations; bundling stores them together. The implementation depends on the HDC model being used, which we’ll discuss in future posts.
Retrieval by similarity
Once information shares a hypervector space, we can retrieve it by similarity rather than by an exact identifier. Let’s say we want to find people interested in hiking. We can construct a query hypervector via the same encoder, composing the same role and value components:
We then compare that cue with stored profile hypervectors using a common distance metric like cosine similarity:
A profile containing the same bound fact about interest and hiking should score higher than an unrelated profile with a different interest.
This is associative search: we obtain a partial cue from the real world and we then look for representations that resemble it in the ways our encoded representation preserves. A full-fledged HDC system uses the same basic idea to retrieve related records or compare structured objects.
Where HDC can be useful
HDC is especially interesting for problems involving:
- Heterogeneous or connected data, where roles and relationships need to survive encoding
- Associative search and memory, where retrieval begins with a partial cue
- Streaming or online learning, where examples arrive over time
- Sensor and edge systems, where compute and energy may be constrained
- Hybrid AI systems, where learned features feed a compositional memory or classification layer
Research and applications span sensor classification, robotics, language, associative memory, and neuromorphic hardware. HDC can also complement other methods. A learned model might produce features that are encoded into a hypervector, for example, while HDC supplies the memory or online learning layer.
Why HDC now?
The ideas behind HDC go back decades and draw on cognitive science and research into distributed representations in the brain. Today, the landscape couldn’t be more different from when these ideas were first proposed. Modern storage and retrieval systems can handle large floating point representations better, while offering better data compression. We can also use highly optimized CPU and GPU kernels that make good use of parallel hardware.
Much of HDC’s algebra comes down to relatively simple element-wise addition or multiplication, along with permutation. The work splits cleanly across an array’s dimensions, so computation is rarely the bottleneck. Add modern storage and information retrieval techniques, coupled with AI agents, and HDC starts to look like a practical foundation to build associative memory systems that can continuously learn, even in compute-constrained environments.
We’ve already seen how those building blocks can model a person’s profile and retrieve it from a partial cue. This leaves an obvious question:
How can one very large hypervector hold several pieces of information without turning them into an indistinguishable blur?
The next post looks at what a hypervector is and how similarity behaves in high-dimensional space.
At HDC Labs, we’re looking at HDC as something practical that we can build with. It gives us a way to bring structured, associative memory into AI systems that solve real problems. We’re going to show how far that can go, so stay tuned! 🚀